Learning & methods · November 2026学习与方法 · 2026 年 11 月
When Should an Agent Think More or Try More?什么时候多想,什么时候多试?
Separate parameter learning, inference-time search and reasoning-mode selection. Spend additional computation where it can change the outcome.把参数训练、推理搜索与思考模式选择分开:同一份预算,应该花在能够改变结果的地方。
1 More thinking, more trials and more training change different things1 多想、多试、多训练,改变的东西不同
一个 Agent 修复失败后,可以再生成几个候选,也可以沿当前方案继续推理,还可以把案例收集起来训练模型。这三种操作都消耗算力,却不在改变同一个对象。先把它们分开,才知道一个改进究竟来自哪里。
训练通过损失与优化器更新参数 ,影响以后遇到任务时的行为;推理时搜索在当前任务内产生、比较或修订多个候选,即使上下文不断变化,模型参数也可以保持固定;思考模式选择决定本次是否展开推理、分配多少预算,它既可以是外部规则,也可以是训练后学到的策略。
After an agent fails to repair an artifact, it can generate more candidates, reason further along its current approach, or collect the case for training. All consume computation, but they change different objects. Distinguishing them is necessary to identify where an improvement comes from.
Training updates parameters through an objective and optimizer, affecting later behaviour. Inference-time search generates, compares or revises candidates for the current task; parameters may remain fixed while context changes. Reasoning-mode selection chooses whether and how much to reason. It can be an external rule or a learned policy.
Static diagram静态图
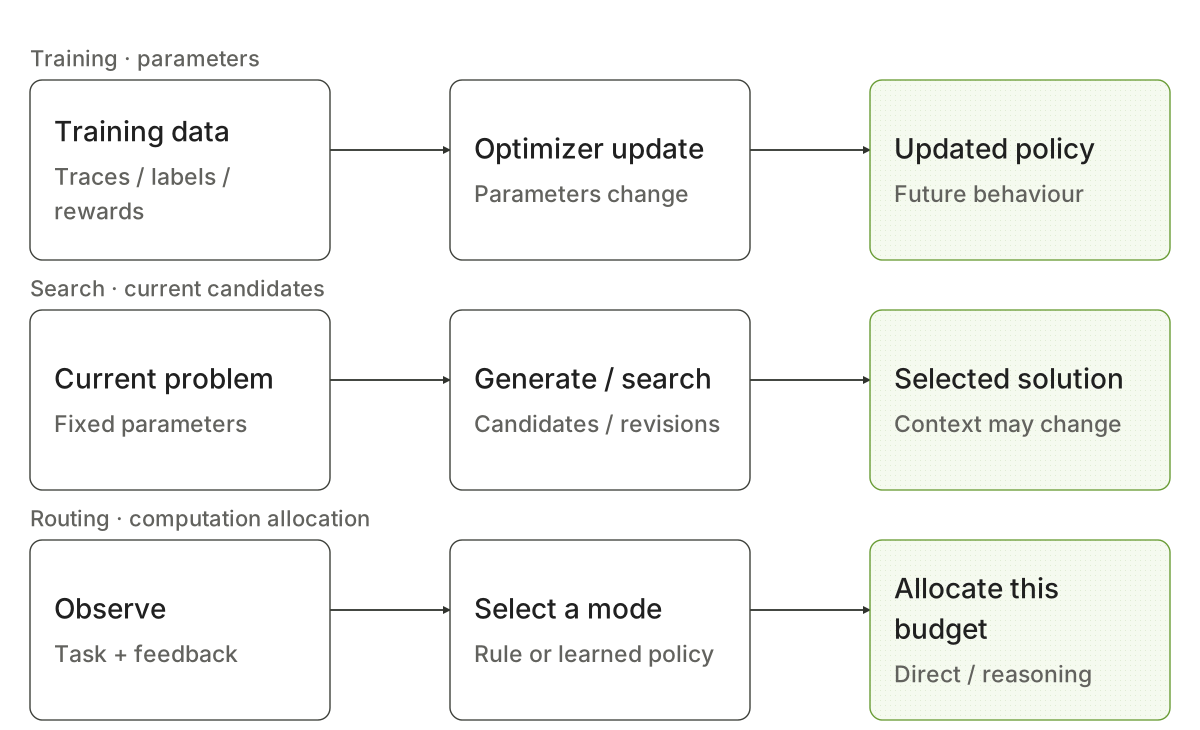
所以,“运行时更会修正”不一定意味着发生了在线训练。模型看到错误后改写答案,可能只是固定参数对新上下文作出响应。判断是否训练,要找参数更新,而不是看对话里有没有反思、奖励或多轮尝试。
Improved correction during execution therefore does not necessarily imply online training. Responding to an error may simply be a fixed model conditioned on new context. To establish training, look for a parameter update, not merely reflection, a reward signal or several attempts in the conversation.
2 Parallel candidates and sequential revisions have different shapes2 多个候选与多轮修订,是两种搜索形状
并行采样从同一问题出发生成多个解法,再选一个;顺序修订把上一次尝试与反馈放进下一轮。前者有机会探索不同方案,后者有机会修补已有方案。树搜索进一步保留多个中间状态,决定扩展哪一支。Tree of Thoughts 展示了这种以文本步骤为搜索单位的组织方法,但不意味着任意任务都需要 MCTS。
《Scaling LLM Test-Time Compute Optimally》在数学问题上比较了并行采样与经过专门训练的修订模型,发现合适比例随难度和预算变化。这个结果的价值是说明预算分配依赖任务;不能把数学上的最优比例当作网页 Agent 的通用配置。其难度估计本身也需要计算,论文明确没有把这部分成本全部计入主要比较。
思考链更长也不等于搜索更广。一条很长的连续推理可能始终沿同一条错误路线;若真正缺少的是另一种解法,应考虑扩大候选覆盖,而非只让同一个方案继续写下去。
Parallel sampling starts several solutions from the same problem and selects one. Sequential revision conditions the next attempt on the previous attempt and feedback. The former can explore different approaches; the latter can refine an existing one. Tree search retains multiple intermediate states and chooses which to expand. Tree of Thoughts illustrates search over textual steps, but it does not imply that every task needs MCTS.
Scaling LLM Test-Time Compute Optimally compares parallel sampling with specifically trained revision models on mathematical tasks. Appropriate allocations vary with difficulty and budget. This supports task-dependent allocation, not a universal configuration for web agents. Difficulty estimation itself also consumes computation; the paper explicitly leaves that additional cost out of its main comparisons.
A longer reasoning trace is not necessarily a broader search. One extended chain can remain on the same mistaken route. If the missing ingredient is an alternative approach, expanding candidate coverage may matter more than continuing the current explanation.
3 Search also depends on how a candidate is selected3 搜索是否有用,还取决于谁来选
设单次采样正确的概率为 。在独立、同分布的简化假设下,采样 次至少出现一个正确答案的概率是 。这只描述候选集合里有没有正确答案,没有保证评审器会把它选出来;真实候选还可能高度相关。
如果同一个 Judge 系统性偏爱某种错误,增加搜索可能只是更善于找到高分错误。上面的 test-time compute 论文观察到了搜索对过程评估器过度优化的例子。因此评估至少要区分候选覆盖、选中结果的正确率与最终执行成功,不能只看“最好的候选曾经达到多少分”。
这是本文用于拆账的示意式,对金额、归一化计算量等可加总资源成立,不宜把不同单位直接相加。并行执行的墙钟延迟应按关键路径或实际计时统计。路由、判断、工具执行和恢复都要入账。少生成一些 token,但多做几次昂贵的环境重置,不一定更省。
If an independent sample is correct with probability , then under an independent, identically distributed simplification, samples contain at least one correct answer with probability . This concerns coverage within the candidate set. It does not guarantee that a judge selects that answer, and real candidates can be strongly correlated.
If a judge systematically rewards a particular error, additional search may become better at finding high-scoring mistakes. The test-time compute paper reports examples of over-optimization against its process verifier. Evaluation should therefore distinguish candidate coverage, correctness of the selected answer and final execution success. The best score ever encountered does not measure all three.
This is a proposed accounting identity for additive resources such as money or normalized computation; different units should not be added directly. Parallel wall-clock latency follows the critical path or measured elapsed time. Routing, verification, tool execution and recovery belong in the ledger. Fewer generated tokens do not guarantee savings if they trigger several expensive environment resets.
4 Adaptive reasoning requires both ability and selection4 自适应思考,需要同时学会能力与选择
Omni-AutoThink 把这件事拆成两步:先用监督数据让模型具备思考与不思考两种输出能力,再用自适应 GRPO 学习选择。其公开方案在训练时强制采样两种模式,并减少部分简单样本的梯度参与;这里“不参与更新”不等于采样没有发生,不能据此宣称省掉了全部生成成本。见论文 第 3 节。
论文的四档奖励也很有启发:直接答对为 2,思考后答对为 1,思考后答错为 0,直接答错为 −1。按这个特定奖励,设直接与思考的正确率分别为 ,则期望奖励分别为:
这说明模式偏好取决于奖励刻度,不是“简单题”标签天然决定。即使思考正确率略高,直接模式仍可能因奖励设计更受偏好。这个算式是对论文奖励表的代数展开,不是生产系统推荐阈值;真实部署需要按任务风险与总成本重新评估。该论文研究多模态回答,尚不能据此宣称逐轮控制工具 Agent 已获验证。
Omni-AutoThink separates acquiring both output modes from learning when to use them. Its adaptive SFT stage supplies thinking and no-thinking examples; adaptive GRPO then forces samples from both modes and masks part of the easy-query samples during updates. Masking a trajectory after sampling does not mean its generation cost disappeared. See Section 3.
The reward table is instructive: a correct no-thinking answer receives 2, a correct thinking answer 1, an incorrect thinking answer 0, and an incorrect no-thinking answer −1. Under this particular table, if the respective correctness probabilities are , their expected rewards are:
Mode preference therefore depends on the reward scale rather than following automatically from an “easy” label. The no-thinking mode can be preferred even when thinking is slightly more accurate. This is an algebraic consequence of the paper's reward table, not a recommended deployment threshold. Actual task risk and total cost require separate evaluation. The paper concerns multimodal answers, so it does not by itself validate turn-by-turn control of a tool-using agent.
5 For agents, start by comparing modes from the same state5 迁移到 Agent,先做同状态的模式比较
要把自适应思考迁移到多轮工具任务,可以提出一个具体可检验的问题:在相同执行状态下,直接继续与增加分析,哪一种带来更好的后续结果?不要把简单任务中的直接动作,与复杂任务中的长思考直接相减,那会混入任务差异。
Transferring adaptive reasoning to multi-turn tool use suggests a testable question: from the same execution state, does proceeding directly or adding analysis produce a better continuation? Comparing direct actions on easy tasks with long reasoning on hard tasks would confound the mode with the task.
Static diagram静态图
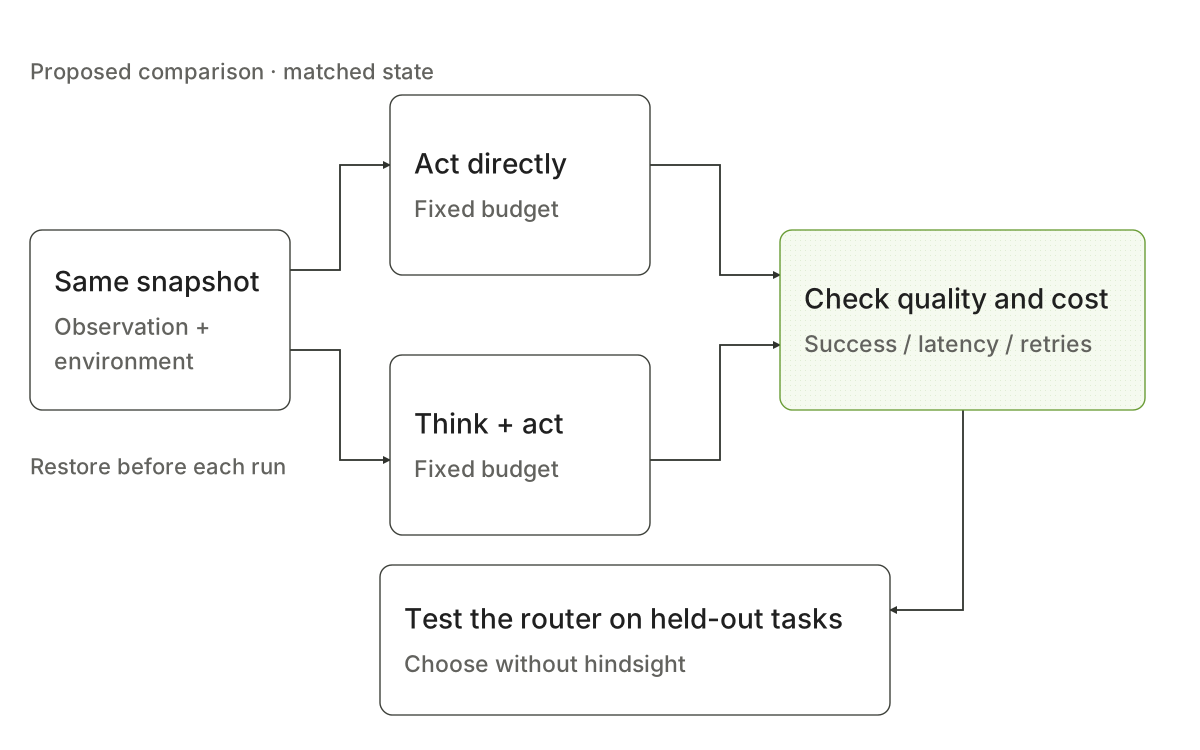
例如,当前观察已经给出正确字段名,直接修正参数也许足够;如果失败涉及跨对象依赖,先分析关系可能避免连续误改。这里“也许”要由试验回答:保存同一环境快照,固定模型版本与后续预算,对两个模式分别续跑,验收最终产物,同时记录重试、延迟和费用。
对具有写副作用的环境,快照必须包含外部数据状态,不能只复制聊天记录。若无法恢复一致状态,应把比较限制在隔离副本或只读任务。图中是本文提出的评测设计,不是 Omni-AutoThink 论文已经报告的 Agent 实验。
If the current observation already identifies the correct field, a direct parameter fix may be sufficient. If failure concerns dependencies across objects, analysis may prevent repeated mistakes. These possibilities need testing: restore the same snapshot, hold the model version and continuation budget fixed, run both modes, and check the final artifact while recording retries, latency and expenditure.
For environments with write side effects, the snapshot must include external data state, not just the chat history. If comparable state cannot be restored, use isolated copies or read-only tasks. The diagram proposes an evaluation design; it is not an agent experiment already reported by Omni-AutoThink.
6 Evaluate the router, not only the two modes6 最后评估路由,而不只评估两个模式
即使知道每道题哪个模式更好,也还没有得到可部署系统。离线试过两种模式再挑最好,是一个事后参照;上线时的路由器只能依据当时可见的观察决定。两者之间的差距,才暴露选择能力是否足够。
设 是在状态 使用模式 的平均质量减成本效用,路由器选 。一个说明性的模式遗憾定义是 。假设验证集反复续跑估计出直接模式效用 0.70、思考模式 0.76,路由器选直接,则遗憾为 0.06。这是教学数值,不是实际测量;单次成功失败也不足以准确估计期望效用。
评测应同时比较固定直接、固定思考、学习路由与事后最佳参照,报告质量—成本曲线,并在独立任务上检验。预算与选择规则在验证阶段确定,最终测试不再按答案调参。若路由开销吞掉节省,或错误选择集中在高风险任务上,就先保留更简单的固定策略。可部署的改进,是在用户真实约束下把预算用对,而不只是平均思考长度变短。
Knowing which mode works best for every task does not yet produce a deployable system. Trying both modes and choosing afterwards is a hindsight reference. A deployed router must decide from information visible at the time. The gap between them reveals how much selection capability is still missing.
Let be expected quality-minus-cost utility for mode from state , and let the router select . An illustrative mode-regret definition is . Suppose repeated validation continuations estimate utility at 0.70 for direct execution and 0.76 for thinking. Choosing direct execution yields regret 0.06. These are teaching values, not measurements; a single successful or failed rollout cannot accurately estimate expected utility.
Compare always-direct, always-thinking, the learned router and the hindsight reference, report quality–cost curves, and evaluate on independent tasks. Choose budgets and routing rules during validation; do not tune them using final-test answers. If routing overhead consumes the savings, or selection errors concentrate on high-risk cases, retain a simpler fixed policy. A deployable improvement allocates computation well under real constraints, rather than merely shortening average reasoning traces.
Continue reading继续阅读
- Scaling LLM Test-Time Compute Optimally · v1
- Tree of Thoughts · v2
- Omni-AutoThink · v1
- 原知识合集:训练与推理搜索
- 原知识合集:Auto-Thinking