Learning & methods · November 2026学习与方法 · 2026 年 11 月
Why Let an Agent Act Through Code?为什么让 Agent 写代码?
CodeAct puts control flow into a program and returns execution feedback to the model. Fewer interactions do not remove the need to verify the result.CodeAct 把控制流交给程序,把环境反馈交还模型。它能压缩交互,但运行成功与任务正确仍是两件事。
1 The first change is the representation of an action1 改变的首先是动作的表达方式
假设用户要汇总三个项目的未完成订单。模型可以逐次调用查询工具,把结果带回上下文,再决定下一次查询与汇总;也可以生成一段代码,循环读取三个项目,在程序里筛选和计算,最后把需要的结果返回。两者都在使用工具,区别在于组合工具的逻辑放在哪里执行。
CodeAct 原论文把可执行 Python 代码作为动作:模型输出程序片段,解释器执行,结果或错误成为下一轮观察。它不是“写完代码就退出”的离线代码生成,而是可持续修正的交互过程。论文的原始实现是 Python;采用 TypeScript、静态类型检查或特定 SDK,是另一层工程选择,不能倒过来当作 CodeAct 的定义。
因此,最有用的问题不是“代码是不是比 JSON 高级”,而是:一个任务需要多少中间组合逻辑、哪些计算应交给解释器,以及哪些决策必须等待新的环境信息。对于单次查天气这样的动作,一个清楚的工具调用已经足够。
Suppose a user asks for a summary of unfinished orders across three projects. An agent can call a query tool repeatedly, bring the results back into its context, and decide how to aggregate them. Alternatively, it can emit code that loops over the projects, filters and sums within the runtime, and returns the required result. Both use tools. The difference is where the composition logic executes.
The original CodeAct paper uses executable Python as the action representation. The model emits a program fragment; the interpreter runs it; results or errors become the next observation. This is an interactive process with opportunities for revision, rather than a one-off code-generation job. TypeScript, static checks and a particular SDK are subsequent engineering choices, not the definition of CodeAct.
The useful question is therefore how much intermediate composition a task requires, what computation belongs in a runtime, and which decisions must wait for new information. A single well-defined tool call is entirely adequate for a simple weather lookup.
2 Code keeps loops, branches and intermediate values in the runtime2 代码把循环、条件和中间变量留在执行器里
下面是一个教学示例。假设 query_orders 是只读工具,返回金额以分为单位的订单列表。目标是按项目汇总未完成金额。循环、条件和累加都有明确的程序语义,不必让模型在每轮对话里手工记住所有中间数字。
totals = {}
for project in ["A", "B", "C"]:
    orders = query_orders(project)
    totals[project] = sum(
        row["amount_cents"] for row in orders
        if row["status"] != "done"
    )
print(totals)
In this teaching example, query_orders is a read-only tool returning orders whose amounts are in cents. The task is to aggregate unfinished amounts by project. Loops, conditions and arithmetic have explicit program semantics, so the model does not need to carry every intermediate number through another conversation turn.
totals = {}
for project in ["A", "B", "C"]:
    orders = query_orders(project)
    totals[project] = sum(
        row["amount_cents"] for row in orders
        if row["status"] != "done"
    )
print(totals)
Static diagram静态图
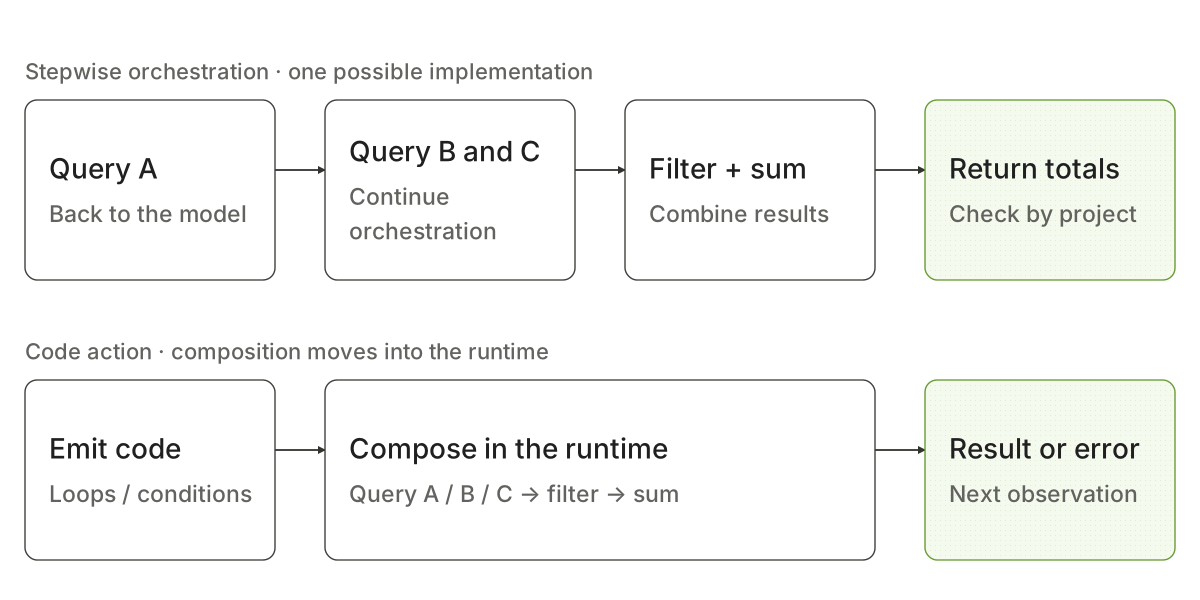
节省的是模型与执行器之间某些往返,以及搬运中间结果的上下文成本;底层查询仍然存在,不能把一次代码执行说成只有一次业务 API 请求。并行与批量工具调用、确定性工作流,也可以实现一部分相同收益。原论文在自己的工具使用任务上比较了动作格式,并不支持“所有场景代码都更优”的结论。
程序还能保留变量与数据结构,减少把结构化结果反复改写成自然语言的损耗。但“所有事一次写完”并非目标:若下一步依赖刚发现的权限或字段语义,就应暂停返回观察,让模型基于新证据决策。
This can save some model–runtime round trips and the context cost of transporting intermediate results. The underlying queries still occur: one code execution does not imply one business API request. Batched or parallel tool calls and deterministic workflows can capture some of the same benefits. The paper's action-format comparisons on its tool-use tasks do not establish universal superiority for code.
Variables and structured data also reduce repeated translation into prose. Yet putting everything in one program is not the goal. When a later action depends on newly discovered permissions or field semantics, execution should return an observation so the model can decide from that evidence.
3 Code actions can sit inside a ReAct loop3 代码动作与 ReAct 可以处在同一个循环里
ReAct 描述推理与行动交替的组织方式,CodeAct 描述动作怎样表示。它们不是二选一的竞争模型:Agent 可以先判断需要哪些信息,输出代码查询,再根据结果修改计划。ReAct 项目强调行动带来的外部信息;CodeAct §2.1则明确把执行输出作为下一轮观察。
如果代码读取不存在的 amount 字段,异常可以指出具体访问位置。模型随后检查返回结构,改用 amount_cents。这里真正有价值的监督是“什么状态下发生了什么错误,以及修复如何改变结果”,而不是仅仅多写一段看似深刻的思考。
不过,异常没有告诉模型所有业务含义。字段名正确,不代表把人民币分与美元分相加就合理;计算跑通,不代表汇总范围符合用户要求。程序错误可以帮助定位,业务正确性仍要由任务合同与产物检查来回答。
ReAct concerns the organization of reasoning and action; CodeAct concerns the representation of actions. They can coexist: the agent identifies missing information, queries it through code, and revises its plan after observing the result. The ReAct project emphasizes information obtained through action; CodeAct §2.1 explicitly treats execution outputs as subsequent observations.
If code accesses a nonexistent amount field, an exception may locate the failing access. The model can inspect the returned structure and replace it with amount_cents. The useful supervision links the state, the error, the repair and the changed result. Merely adding a longer explanation does not establish this connection.
An exception cannot supply every business meaning, however. Correct field access does not justify adding amounts in different currencies. A program that runs can still aggregate the wrong scope. Runtime feedback helps locate program errors; a task contract and artifact checks establish whether the requested job was done.
4 Separate static validity, execution and task correctness4 静态检查、执行成功、任务完成,要分开判定
在带类型的实现中,静态检查可以提前发现部分参数、类型和 API 使用错误。这里也要准确理解 TypeScript:它的类型在生成 JavaScript 时被擦除;默认的编译行为不一定因报错停止生成文件。若要用它作为执行闸门,工程上需要显式检查退出状态或采用相应配置。参见 官方 Handbook。
In a typed implementation, static checks catch some invalid parameters, types and API uses before execution. TypeScript's behaviour needs precision: types are erased when JavaScript is emitted, and its default compiler behaviour does not necessarily stop emission when errors occur. Using it as an execution gate requires explicitly checking the exit status or applying the relevant compiler configuration. See the official Handbook.
Static diagram静态图
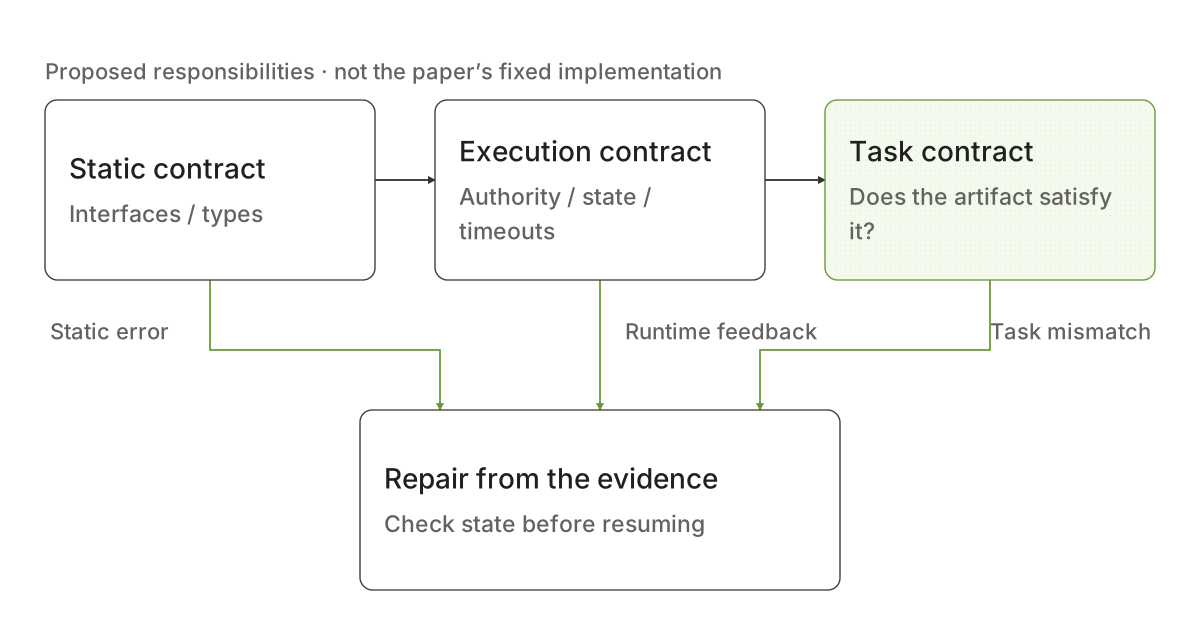
第二层是执行合同:在什么环境、以什么权限、调用哪些接口,如何处理超时与部分成功。第三层才是任务合同:产物是否包含要求的数据关系,范围与结果是否正确。三层检查回答不同问题,不能拿“编译通过”代替“工作已完成”。
同样,dry run 的含义取决于实现。它可能只做语法检查,也可能计算差异,或在隔离副本里完整执行。只有明确测试了什么,返回结果才有解释力。下图是本文提出的工程分层,用来拆清责任,并非声称 CodeAct 论文自带这一套 TypeScript 管线。
The second contract concerns execution: environment, authority, available interfaces, timeouts and partial success. The third concerns the task: whether the resulting artifact has the requested relationships, scope and results. These checks answer different questions. Compilation is not task completion.
Likewise, dry run can mean syntax checking, computing a change plan, or full execution against an isolated copy. Its result is meaningful only when that behaviour is specified. The diagram is a proposed engineering decomposition; it is not a claim that the original CodeAct paper implements this TypeScript pipeline.
5 A retry must account for effects that already happened5 失败后的重试,不能假设环境还是原样
只读查询容易重试,写操作需要更小心。假设一段程序依次“建项目 → 建任务 → 建视图”,第二步超时。超时可能表示操作失败,也可能只是成功响应没有送到。直接重跑整段程序,可能创建两个项目;只看最后一条报错,也不知道前面已经完成了多少。
可行的工程做法是为步骤保存稳定标识与已确认结果,重试前查询实际状态;必要时使用接口提供的幂等键或显式补偿。沙箱能限制程序运行边界,但不会自动撤销远端系统已经发生的写入。日志里的“计划回滚”也不等于环境已经恢复。
这与轨迹训练直接相关。若模型观察到的是部分成功状态,修复样本就应从该状态继续;如果评估要求每个候选从同一初始状态比较,就必须真的恢复环境。状态恢复是执行器的职责,不能靠在提示词里补一句“假设从头开始”完成。
Read-only queries are often straightforward to retry; writes require more care. Consider a program that creates a project, creates its tasks, and creates a view. A timeout during the second step may mean failure, or merely that a successful response was lost. Rerunning the whole program can create a duplicate project. The final exception alone does not describe how much already succeeded.
An engineering approach is to record stable step identifiers and confirmed results, inspect actual state before retrying, and use API-supported idempotency keys or explicit compensation where appropriate. A sandbox restricts execution boundaries but does not automatically undo writes to a remote service. A logged intention to roll back is not a restored environment.
This matters for training traces. A repair example should continue from the partially successful state the agent actually observes. If candidate evaluations require identical initial conditions, the runtime must genuinely restore them. A prompt asking the model to “assume a fresh start” cannot perform that restoration.
6 Choose an interface for the structure of the task6 按任务结构选择接口,而不是按名字选架构
接口稳定、参数少、单步责任清楚时,结构化工具调用通常容易验证;有大量循环、条件、数据转换与库调用时,代码动作更容易表达;权限敏感、过程固定的重复操作,则适合把可变空间收进确定性工作流。这些可以组合,例如模型只生成一个受约束的查询程序,最终写入由专门工具执行。
采用代码接口也不意味着“SDK 新增一个函数,模型自然就会用”。模型仍需要接口说明、合适示例、运行反馈和覆盖新功能的评测。Python 也有类型检查工具;Node.js 是否更快、镜像是否更小,取决于运行栈与依赖,不能由语言名称推断。
可以从一个只读任务做比较:固定任务与底层 API,记录完成率、模型往返次数、执行器请求数、上下文体积和总耗时。若代码形式只是把错误藏进更大的动作块,就应拆小;若它让中间计算可靠且可检查,再扩大使用范围。好的动作表示,应让执行更清楚,反馈更可用。
Stable interfaces with few arguments and a clear single-step responsibility suit structured tool calls. Tasks involving loops, conditions, transformations and libraries often suit code actions. Sensitive, repetitive operations with a fixed procedure may fit a deterministic workflow. These choices can be combined: a constrained query program can gather evidence while a dedicated tool performs the final write.
A code interface does not mean that adding an SDK function automatically teaches the model to use it. Documentation, examples, runtime feedback and evaluation coverage remain necessary. Python also supports type-checking tools; runtime startup and image size depend on the actual stack and dependencies, not the language name alone.
A useful first comparison holds a read-only task and underlying API fixed, measuring success, model round trips, runtime requests, context volume and total latency. If code merely hides failures inside a larger action, split it into smaller observable steps. If it makes intermediate computation reliable and inspectable, expand its role. A good action representation makes execution clearer and feedback more useful.
Continue reading继续阅读
- Executable Code Actions Elicit Better LLM Agents · v3
- ReAct · official project
- TypeScript Handbook · The Basics
- 原知识合集:CodeAct 与 Agent 工程
- Original study notes原始学习笔记 · auto thinking